Prediction (out of sample)#
[1]:
%matplotlib inline
[2]:
import matplotlib.pyplot as plt
import numpy as np

import statsmodels.api as sm

plt.rc("figure", figsize=(16, 8))
plt.rc("font", size=14)
Artificial data#
[3]:
nsample = 50
sig = 0.25
x1 = np.linspace(0, 20, nsample)
X = np.column_stack((x1, np.sin(x1), (x1 - 5) ** 2))
X = sm.add_constant(X)
beta = [5.0, 0.5, 0.5, -0.02]
y_true = np.dot(X, beta)
y = y_true + sig * np.random.normal(size=nsample)
Estimation#
[4]:
olsmod = sm.OLS(y, X)
olsres = olsmod.fit()
print(olsres.summary())
                            OLS Regression Results
==============================================================================
Dep. Variable:                      y   R-squared:                       0.983
Model:                            OLS   Adj. R-squared:                  0.982
Method:                 Least Squares   F-statistic:                     891.5
Date:                Thu, 27 Aug 2026   Prob (F-statistic):           9.63e-41
Time:                        06:56:15   Log-Likelihood:                0.60925
No. Observations:                  50   AIC:                             6.781
Df Residuals:                      46   BIC:                             14.43
Df Model:                           3
Covariance Type:            nonrobust
==============================================================================
                 coef    std err          t      P>|t|      [0.025      0.975]
------------------------------------------------------------------------------
const          5.0275      0.085     59.186      0.000       4.856       5.198
x1             0.4763      0.013     36.356      0.000       0.450       0.503
x2             0.4568      0.051      8.869      0.000       0.353       0.560
x3            -0.0176      0.001    -15.319      0.000      -0.020      -0.015
==============================================================================
Omnibus:                        0.591   Durbin-Watson:                   2.149
Prob(Omnibus):                  0.744   Jarque-Bera (JB):                0.217
Skew:                           0.152   Prob(JB):                        0.897
Kurtosis:                       3.109   Cond. No.                         221.
==============================================================================

Notes:
[1] Standard Errors assume that the covariance matrix of the errors is correctly specified.
In-sample prediction#
[5]:
ypred = olsres.predict(X)
print(ypred)
[ 4.58696428  5.031648    5.44067341  5.78914709  6.06115952  6.25239896
  6.3708599   6.43552955  6.47326831  6.51439667  6.58771367  6.71576526
  6.91114008  7.1744012   7.49399358  7.84814256  8.20843133  8.54446979
  8.82888751  9.04183065  9.17422384  9.22926131  9.22188201  9.17631524
  9.12209981  9.08923094  9.10323206  9.18096145  9.32784244  9.53697237
  9.79025671 10.06138189 10.32013858 10.537385   10.68983479 10.76388295
 10.75784108 10.68221476 10.55797752 10.41312499 10.27807523 10.18067119
 10.14160614 10.17102388 10.26685208 10.41514281 10.59236412 10.76926627
 10.91568741 11.00550904]
Create a new sample of explanatory variables Xnew, predict and plot#
[6]:
x1n = np.linspace(20.5, 25, 10)
Xnew = np.column_stack((x1n, np.sin(x1n), (x1n - 5) ** 2))
Xnew = sm.add_constant(Xnew)
ynewpred = olsres.predict(Xnew)  # predict out of sample
print(ynewpred)
[11.01325842 10.9007197  10.68580557 10.40933682 10.12504794  9.88643107
  9.73363928  9.68365563  9.72613521  9.82593786]
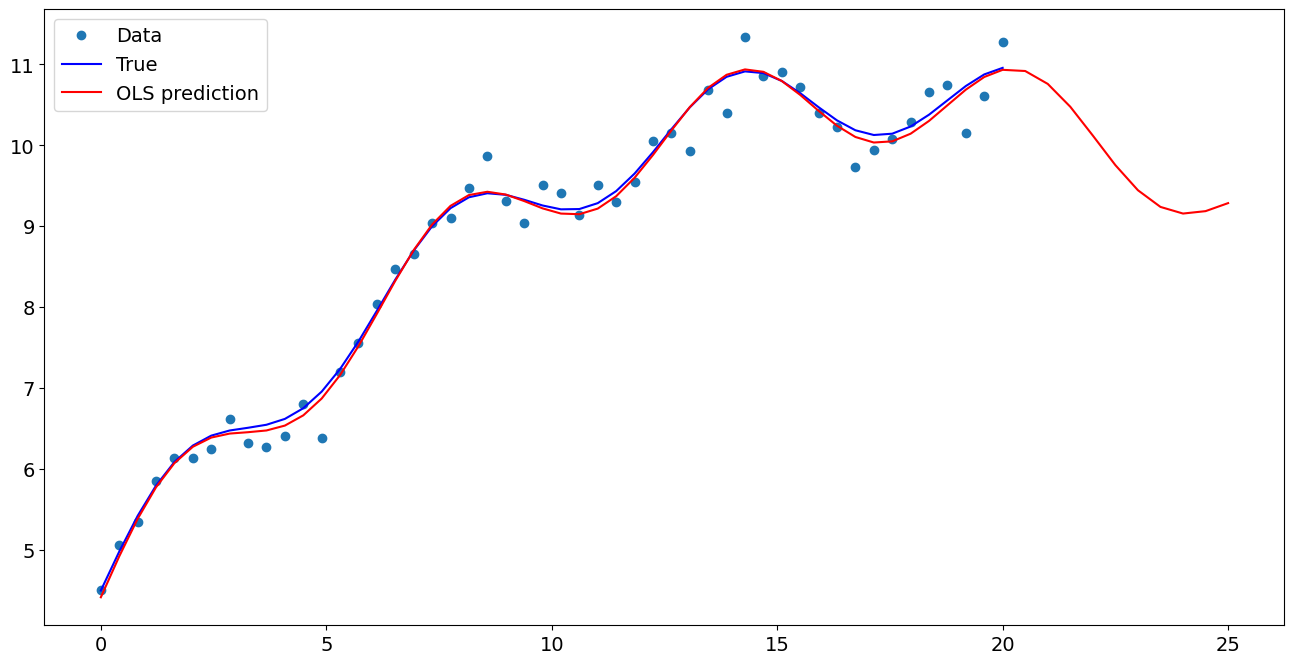
Plot comparison#
[7]:
import matplotlib.pyplot as plt

fig, ax = plt.subplots()
ax.plot(x1, y, "o", label="Data")
ax.plot(x1, y_true, "b-", label="True")
ax.plot(np.hstack((x1, x1n)), np.hstack((ypred, ynewpred)), "r", label="OLS prediction")
ax.legend(loc="best")
[7]:
<matplotlib.legend.Legend at 0x7f1ba0d13b60>
Predicting with Formulas#
Using formulas can make both estimation and prediction a lot easier
[8]:
from statsmodels.formula.api import ols

data = {"x1": x1, "y": y}

res = ols("y ~ x1 + np.sin(x1) + I((x1-5)**2)", data=data).fit()
We use the I to indicate use of the Identity transform. Ie., we do not want any expansion magic from using **2
[9]:
res.params
[9]:
Intercept           5.027464
x1                  0.476277
np.sin(x1)          0.456768
I((x1 - 5) ** 2)   -0.017620
dtype: float64
Now we only have to pass the single variable and we get the transformed right-hand side variables automatically
[10]:
res.predict(exog=dict(x1=x1n))
[10]:
0    11.013258
1    10.900720
2    10.685806
3    10.409337
4    10.125048
5     9.886431
6     9.733639
7     9.683656
8     9.726135
9     9.825938
dtype: float64